Your Multi-Day Agent Job Has No Audit Trail. A $100 Drive Fixes That.
Anthropic's Fermat's Last Theorem formalization was trustworthy without human review because every line was checked and kept. Most small-shop agent jobs have no independent record of what actually happened during a long unsupervised run — just the agent's own summary. A dedicated portable SSD as a local, append-only log target closes that gap for about $100.
Disclosure: some links below are Amazon affiliate links (tag cao04-20). Costs you nothing; the picks don’t change based on that. Every spec and price below is sourced at the bottom.
Note: This runs alongside today’s piece on Claude’s 11-day autonomous Fermat’s Last Theorem formalization. That piece’s actual conclusion: the reason 13 million lines of unreviewed code could be trusted wasn’t the AI’s capability, it was that every line was mechanically checked and kept, permanently, for anyone to re-verify. Most small-shop agent jobs have no equivalent record. This is the cheap fix for that specific gap.
Here’s the question that “the agent finished the job” doesn’t actually answer: what did it do to get there? Most agent harnesses give you a final summary — a chat message, a completion status, a “done, here’s what changed” — and that summary is the thing under test reporting on itself. It’s not an independent record. If the agent’s own account of an 11-day migration job, a multi-day data cleanup, or a long autonomous coding session is the only record that exists, you don’t actually know what happened during those 11 days. You know what the agent chose to tell you about them.
Claude’s Fermat’s Last Theorem proof didn’t have this problem, because Lean’s compiler checked and preserved every one of 13 million lines as they were written — a permanent, independently re-checkable record that exists whether or not anyone trusts the agent’s summary. Most small-shop automation has nothing like that. A dedicated portable SSD, used specifically as a local, append-only target for full agent logs and intermediate outputs — not just the final summary — is the closest cheap equivalent a small shop can actually set up.
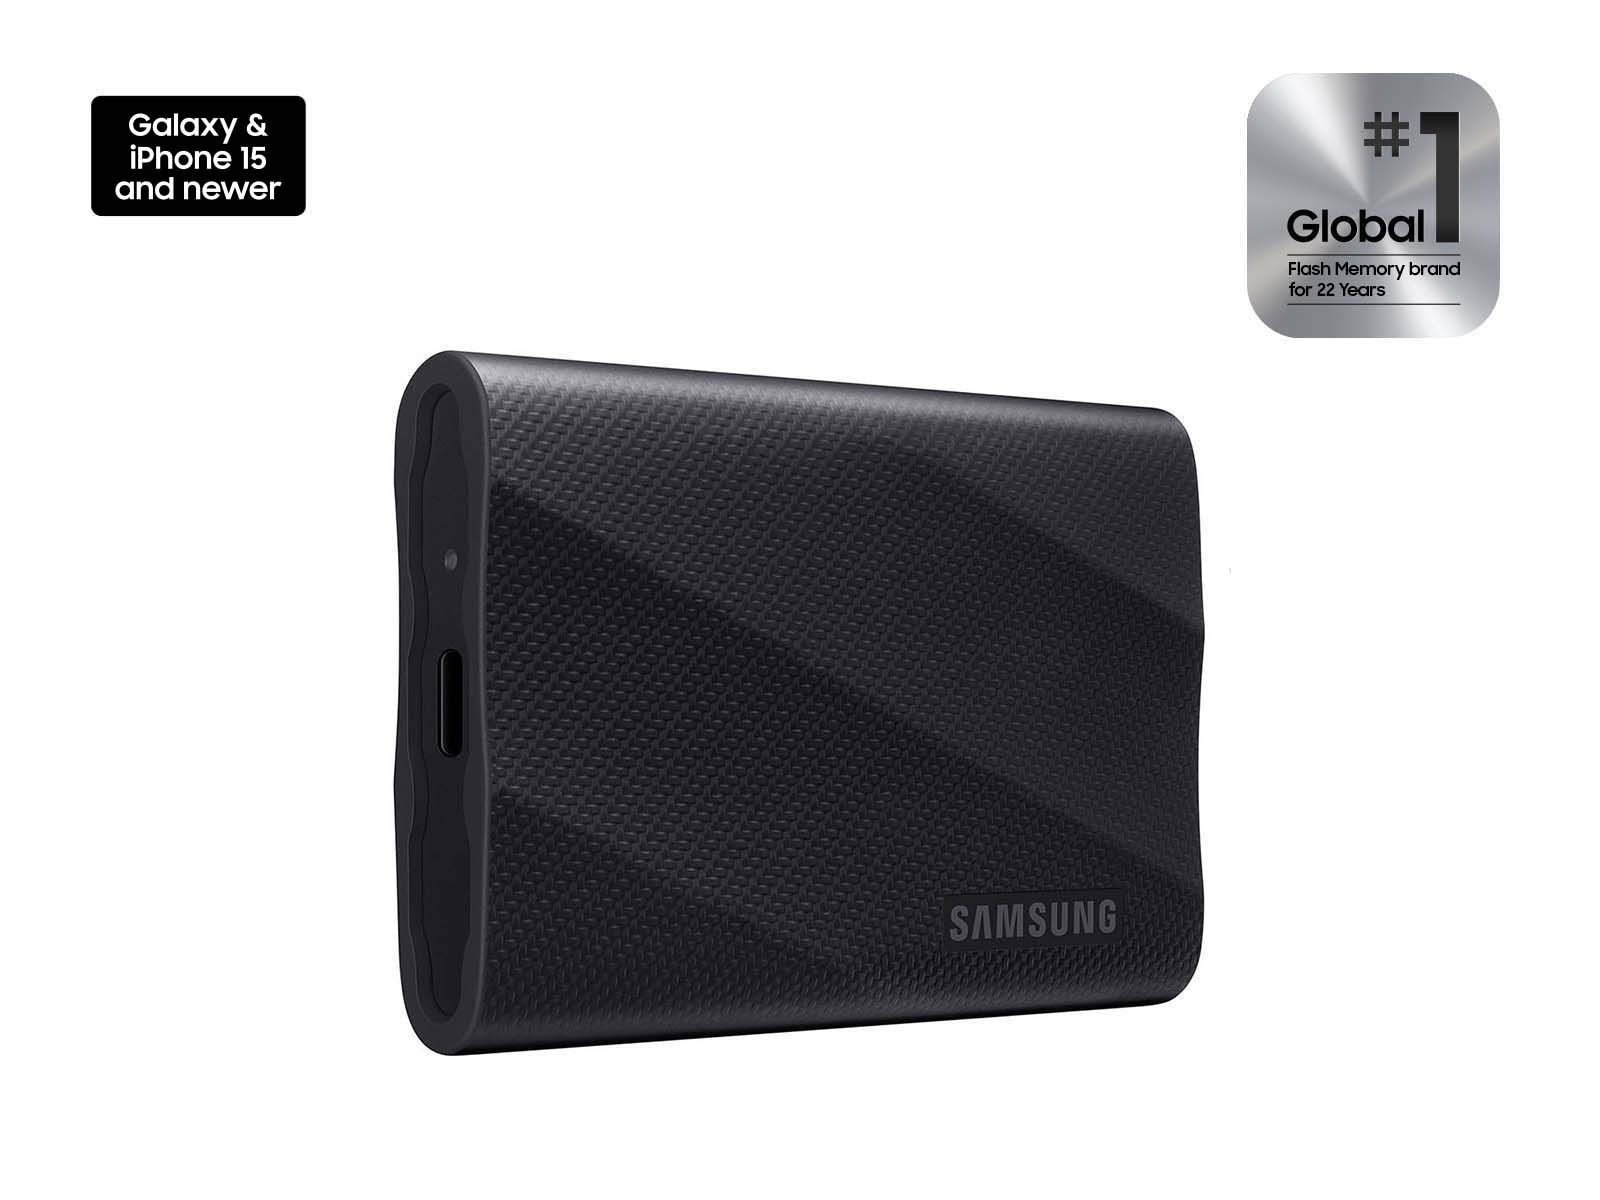
The pick: Samsung T9 Portable SSD
| Spec | Detail |
|---|---|
| Capacity options | 1TB, 2TB, 4TB |
| Speed | Up to 2,000MB/s read and write |
| Interface | USB 3.2 Gen 2×2 |
| Durability | Rated for drops up to 9.8 feet |
| Thermal management | Dynamic Thermal Guard — sustains speed under long write sessions instead of throttling quickly |
| Price | Around $100–140 for 1TB (MSRP $139.99; frequently discounted) |
Sources: Samsung’s official T9 product page, Samsung’s official newsroom announcement.
Check current Samsung T9 pricing here.
Prices on drives like this fluctuate more than most hardware on this site — the T9 has seen repeated Amazon clearance-style price drops since launch. Check current pricing before assuming the MSRP above is what you’ll actually pay; it’s frequently lower.
Choosing a capacity, honestly
1TB is enough for the overwhelming majority of readers here, and it’s worth being direct about why before the 2TB or 4TB upsell tempts you into overspending. Text-based logs — tool calls, timestamps, diffs — are tiny relative to modern drive capacities; even a genuinely verbose multi-day agent session logging every call in full produces megabytes, not gigabytes, of text. Where capacity actually matters is if you’re also snapshotting large intermediate data — full database dumps, image sets, large file trees — at every checkpoint rather than just the metadata about what changed. If that’s your use case, size up to 2TB; if it’s mostly text logs and diffs, 1TB has room to spare for a long time. Don’t buy 4TB “to be safe” for a workload that’s fundamentally about logging small, structured records — that’s paying for headroom you’ll never use.
If you don’t need T9-level speed: honest alternatives
The T9 is the pick here because of its interface, not because it’s the only drive that would work. It runs USB 3.2 Gen 2×2 — real 20Gbps bandwidth — and hits roughly 1,566MB/s sustained sequential reads and 1,581MB/s sustained writes in independent benchmarks, with short bursts touching the advertised 2,000MB/s. That headroom matters specifically if you’re logging verbose tool-call output or writing full intermediate data snapshots in real time and don’t want the logging itself competing for I/O with the job it’s recording.
| Drive | Interface / sustained speed | Durability | Price (1TB) | Best fit |
|---|---|---|---|---|
| Samsung T9 (this pick) | USB 3.2 Gen 2×2, ~1,566–1,581MB/s sustained | Rubberized shell, rated for 3m drop resistance, no IP water rating | ~$100–140 | High-volume verbose logging, real-time intermediate snapshots |
| Samsung T7 Shield | USB 3.2 Gen 2, ~890–950MB/s sustained | IP65 rated (dust and water resistant), rugged shell | ~$90–100 | Same use case, tighter budget, more physical durability if the drive travels or lives somewhere dusty |
| SanDisk Extreme Portable V2 | USB 3.2 Gen 2, ~890–950MB/s sustained | IP55 rated | ~$90–100 | Longest warranty in the category; good default if you’re indifferent between the two above |
If your logging is mostly small structured text — tool calls, diffs, timestamps — any of the three is genuinely fine, and the T7 Shield or SanDisk Extreme save you $20–40 for a use case that doesn’t need the T9’s extra throughput. The T9 earns its price premium specifically when the drive is also catching large intermediate snapshots (full data dumps, image sets) at every checkpoint, where the slower drives’ sustained write speed can become the bottleneck during a busy logging window.
Why a dedicated drive, not just “log to the cloud” or “log to the same machine”
Two obvious alternatives exist, and both have a real gap that a dedicated local drive closes:
Logging to the same machine the agent is running on means the log lives on the exact system whose behavior you’re trying to independently verify. If that machine has a problem — a crash, a runaway process filling disk, a compromise — your record of what happened is sitting on the compromised or crashed system, which is a bad place for the one thing you need to still be trustworthy afterward.
Logging to a cloud service solves that specific problem but introduces dependency and cost: ongoing storage fees, a network dependency during the run (if connectivity drops, does logging silently stop, or does the job stop?), and a third party now holding a full record of everything your agent did — which may include sensitive intermediate data you’d rather not have living in someone else’s infrastructure by default.
A dedicated external SSD, physically separate from the machine under test, plugged in specifically to receive full logs and intermediate outputs, sidesteps both: it’s independent of the machine’s own health, and it’s fully under your control with no ongoing fee or third-party access.
What to actually log, not just that you’re logging
The Fermat proof’s trustworthiness came from what got checked and kept — every logical step, not a summary of steps. The equivalent discipline for a small shop’s agent jobs:
- Every tool call and its result, not just the agent’s narrative about them. If the agent’s harness supports verbose or debug-level logging, turn it on for anything running unsupervised for more than a couple of hours. The narrative summary is a lossy compression of what actually happened; the raw call log isn’t.
- Intermediate outputs at meaningful checkpoints, not just the final result. For a multi-day migration or data-processing job, writing intermediate state to the drive at regular intervals means a problem discovered on day 9 doesn’t require re-running from day 1 to find out when it started.
- Timestamps on everything. A log with no timing information can’t answer “was the agent actually working during this window, or stalled” — which matters for exactly the kind of anomaly detection covered in the smart-plug piece.
- The actual diffs or changes made, not a description of them. “Updated the pricing logic” is the agent’s summary. The actual code diff, the actual before/after data, is the independently verifiable record — the equivalent of Lean checking the literal lines instead of trusting a description of what they do.
A worked comparison: two versions of the same multi-day job
Take the migration scenario from the Fermat piece — a multi-day SKU migration for an e-commerce shop. Version one: the agent runs over a long weekend, and Monday morning the only record is its own chat summary — “migration completed successfully.” If a pricing error surfaces three weeks later on a specific product line, there’s no way to independently reconstruct what happened during the run, what data existed at each stage, or whether the error was introduced on hour 4 or hour 40. The only path forward is guessing, or re-running the whole migration from scratch and hoping the bug reproduces.
Version two: the agent’s full tool-call log, intermediate SKU snapshots at regular checkpoints, and the actual before/after diffs for every changed record were written continuously to a dedicated external drive throughout the run. The same error, surfaced three weeks later, is now a search problem instead of a guessing problem — pull up the checkpoint nearest the affected SKU, find the exact diff that changed its price, and know definitively whether the bug was in the source data, the agent’s transformation logic, or something introduced downstream after the migration finished. That difference — search versus guess — is the entire value of the drive, and it costs about $100 once.
Setup that actually gets used
A logging drive that requires manual intervention to use correctly won’t get used correctly at 2am on day 9 of an 11-day job. The setup that survives contact with reality:
- Mount the drive and point the agent harness’s log output at it before the job starts — not as a manual step to remember mid-run, but configured as the default target for anything expected to run more than a couple of hours unsupervised.
- Keep it physically connected to a machine that isn’t the one under test, if your setup allows it — a small always-on box or even a second cheap machine that just receives logs, so a crash on the primary agent box doesn’t also take out the drive’s connection.
- Don’t reuse the drive for anything else. The same discipline as the smart-plug piece’s “don’t share the outlet” advice — a drive that’s also your general-purpose backup target gets cluttered, and finding the specific log from a specific job three weeks later gets harder every time something unrelated gets copied onto it.
- Periodically verify the logs are actually landing on it, not just configured to. A logging setup that silently stopped working on day 2 of an 11-day job is worse than no logging setup, because it creates false confidence that a record exists.
Scaling past one machine’s worth of logs
Once you’re running agent jobs across more than one machine — a coding agent on one box, a computer-use agent on another, maybe a scraper or data pipeline on a third — the temptation is to point all of them at the same drive with everything dumped into one folder. Resist that specifically: create a clearly named subfolder per job type or per machine (“migration-agent-logs,” “scraper-logs,” not a shared dump), the same labeling discipline that matters for smart plugs and isolated agent networks alike. A single 1TB drive has plenty of room to serve several machines’ worth of text-based logging without needing to upgrade capacity — the organizational discipline matters more than the storage ceiling at this scale. If you eventually outgrow a single portable drive’s worth of organized logging — enough concurrent agent jobs that you want centralized search across all of them rather than browsing folders by hand — that’s the point to look at a proper log-aggregation setup, but very few small shops actually reach that volume before outgrowing something else in their stack first.
How long to actually keep this stuff
A drive that fills up with two years of undifferentiated logs is nearly as unhelpful as one with no logs, because “search the drive” stops being fast once it’s a dumping ground with no structure. A retention policy that actually gets followed, not an aspirational one:
- Keep full verbose logs for the length of your longest realistic “something surfaces late” window. For most small-shop use cases, that’s 60–90 days — long enough to cover the SKU-pricing-error-found-three-weeks-later scenario above, short enough that the drive doesn’t become an archive project. If your industry has a specific record-retention requirement (financial records, healthcare-adjacent data), that number overrides the default.
- Compress and archive past that window instead of deleting outright, if storage headroom allows — a zipped folder of month-old logs takes a fraction of the space of the live version and still answers “what happened” if something surfaces unusually late.
- Never let the retention policy be “whenever the drive fills up, delete the oldest stuff automatically.” That turns your audit trail into a lottery — the log you need might be the one that just got silently purged the week before you needed it. A manual or scheduled review-then-archive step, even a lightweight one, beats a capacity-triggered auto-delete every time.
If your agent jobs touch customer data, treat this retention question with the same seriousness as any other place customer information lives — encrypt the drive at rest (BitLocker To Go on Windows or FileVault’s external-disk encryption on macOS both handle this natively, no extra software required), keep it physically secured when not connected, and don’t let “it’s just logs” talk you out of applying the same data-handling discipline you’d apply to the systems the logs are describing.
What this doesn’t replace
It doesn’t replace an actual review of the logs. A drive full of unread logs is not meaningfully different from no logs at all until someone actually looks at them — either after a problem surfaces, or on a regular check-in cadence. The sandbox box piece covers the habit of periodic review; this is the thing that makes that review possible after the fact, not a substitute for doing it.
It doesn’t replace a mechanical verification check where one is possible. The Fermat piece’s actual recommendation — build the closest available equivalent to Lean’s compiler, a checksum, a count comparison, an automated assertion — is a stronger guarantee than a log you have to manually inspect. Use both where you can; the log is what you fall back on when no automated check exists yet.
It doesn’t make a bad agent job into a good one. Nothing here prevents an error from happening. It only ensures that when one is discovered, you can find out what actually happened instead of guessing.
When not to buy this
If your agent jobs are already short and supervised. A session you’re watching in real time doesn’t need a separate logging drive — you’re the log.
If your agent harness already writes comprehensive logs to a location you trust and control (a dedicated logging server, a properly configured cloud bucket with retention you’re comfortable with), you already have this covered. Don’t add redundant hardware for a problem you’ve already solved.
If the jobs you’re running unsupervised are low-stakes and easily re-run. A drive full of detailed logs matters most for jobs that are expensive, slow, or impossible to cleanly re-run if something goes wrong. A five-minute job that’s trivial to retry doesn’t need this level of record-keeping.
If you need long-term archival storage, not active job logging. A portable SSD is fast and durable but not the cheapest option per terabyte for years of cold storage — the NAS piece is the better fit for that use case.
Quick answers
Does this need to be a Samsung T9 specifically, or would any external drive work? Any reasonably fast, reasonably durable external drive works for the core idea. The T9’s speed matters if you’re logging high-volume verbose output or intermediate data snapshots in real time without wanting the logging itself to become a bottleneck; for lighter logging needs, a cheaper drive is fine.
How much storage do I actually need for this? Depends entirely on log verbosity and job length, but 1TB is generous headroom for text-based logs and periodic data snapshots across many jobs — you’re very unlikely to fill it with logging alone before you fill it with something else you shouldn’t be storing there.
Should this data be encrypted? If your agent jobs touch customer data, yes — treat the logging drive with the same data-handling discipline as any other place customer information ends up, including encryption at rest and physical security for the drive itself.
Doesn’t this just move the trust problem from the agent’s summary to the log itself? Partially, yes — a sufficiently sophisticated failure could produce a log that lies about what happened too. But for the overwhelming majority of real small-shop failure modes (bugs, edge cases, unexpected data, not adversarial deception), an independent log of actual tool calls and diffs is meaningfully harder to accidentally get wrong than a narrative summary generated after the fact.
Bottom line
Claude’s Fermat’s Last Theorem proof was trustworthy without a human reading 13 million lines because every line was mechanically checked and permanently kept — an independent record that exists whether or not anyone trusts the agent’s account of its own work. Most small-shop agent jobs have no equivalent, just a final summary from the system under test. A $100 dedicated drive, configured as the default target for full logs and intermediate outputs on anything running unsupervised for more than a couple of hours, is the cheap version of the same idea: when something needs checking three weeks later, you want a record to search, not a summary to trust.
See current Samsung T9 pricing on Amazon.
Sources
All prices and specs accessed September 7, 2026.
- Official specifications, capacity options, and pricing — Samsung T9 Portable SSD official product page
- Original product announcement and durability/performance claims — Samsung Newsroom, “Samsung Announces T9 Portable SSD”
- Verification methodology this piece is responding to, cited for context — Anthropic, “Formalizing Fermat’s Last Theorem”
- T9 sustained-speed benchmarks and comparison against T7 Shield / SanDisk Extreme (interface, IP ratings, pricing) — StorageReview.com, “Samsung T9 Portable SSD Review”